Exercise 3.3.3
Policy iteration: ε-soft policies, tie-breaking, action-value version
Consider the policy iteration algorithm for estimating \(\pi \approx \pi_*\).
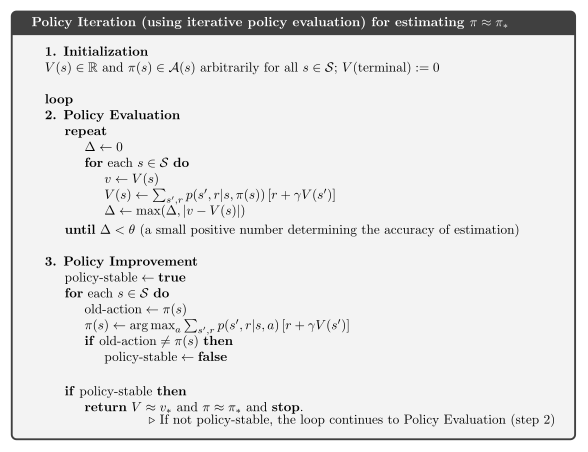
-
(a) Suppose you are restricted to considering only policies that are \(\epsilon\)-soft, meaning that the probability of selecting each action in each state, \(s\), is at least \(\epsilon/|\mathcal{A}(s)|\). Describe qualitatively the changed that would be required in each steps 3,2, and 1, in that order, of the policy iteration algorithm for \(v_*\).
-
(b) The above policy iteration algorithm has a subtle bug in that it may never terminate if the policy continually switches between two or more policies that are equally good. Modify the pseudocode so that convergence is guaranteed.
-
(c) How would policy iteration be defined for action values? Give a complete algorithm for computing \(q_*\), analogous to the pseudocode above for computing \(v_*\).
Source: Sutton & Barto (2018), Reinforcement Learning: An Introduction, 2nd ed., Exercises 4.6, 4.4 and 4.5. Licensed CC BY-NC-ND 2.0.