Exercise 2.4.2
Bellman expectation equations: numeric check at a gridworld state valued +3.0
Consider a simple rectangular gridworld representation of a simple finite MDP as shown in Figure 1. The cells of the grid correspond to the states of the environment. At each cell, four action are possible: \(\texttt{north}, \texttt{south}, \texttt{east},\) and \(\texttt{west}\), which deterministically cause the agent to move one cell in the respective direction on the grid. Actions that would take the agent off the grid leave its location unchanged, but also result in a reward of \(-1\). Other actions result in a reward of \(0\), except those that move the agent out of the special states \(A\) and \(B\). From state \(A\), all four actions yiled a reward of \(+10\) and take the agent to \(A'\). From state \(B\), all actions yield a reward of \(+5\) and take the agent to \(B'\).
The Bellman equation \[v_{\pi}(s) = \sum_a \pi(a|s) \sum_{s',r} p(s',r|s,a) [r + \gamma v_{\pi}(s')]\] must hold for each state for the value function \(v_{\pi}\) shown in Figure 1. Show numerically that this equation holds for the state, valued at \(+3.0\), with respect to its four neighbouring states, valued at \(+1.5, +8.8, +2.3\), and \(+0.7\). (These numbers are accurate only to one decimal place.)
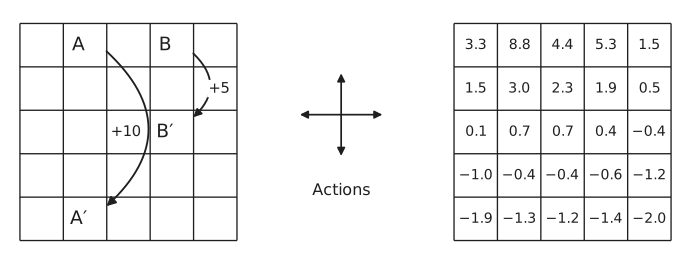
Adapted from Sutton & Barto (2018), Reinforcement Learning: An Introduction, 2nd ed., Exercise 3.14; Example 3.5. Figure 3.2 is redrawn with recomputed values. Licensed CC BY-NC-ND 2.0.