Exercise 1.5.4
ε-greedy: long-run best method in the 10-armed testbed figure
In the comparison shown in Figure 1, which method will perform best in the long run in terms of cumulative reward and probability of selecting the best action? How much better will it be? Express your answer quantitatively.
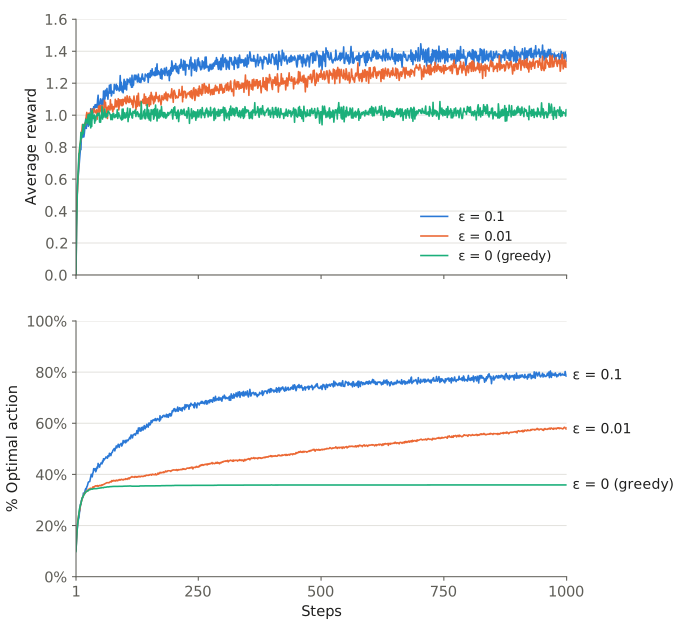
Source: Sutton & Barto (2018), Reinforcement Learning: An Introduction, 2nd ed., Exercise 2.3. Figure 2.2 is redrawn from a new run of the book's experiment. Licensed CC BY-NC-ND 2.0.