Exercise R.3.1
Expected value: return of policies in a three-cell corridor
Consider the environment:
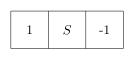
Assume the agent starts in the middle cell (\(S\)). If the agent receives a reward, the episode ends. The left cell gives a reward of 1, and the right cell of -1. Let \(L\) and \(R\) denote the only possible actions, namely left and right.
-
What is the expected return of the following policies given the starting state \(S\)?
\(\pi(L \mid S)=0.4\)
\(\pi(L \mid S)=0.2\)
\(\pi(R \mid S)=0.6\)
-
The expected value of the return from a policy given the starting state \(S\) is 0.5. What is the policy?
-
What is the policy that maximizes the expected return? Is it stochastic or deterministic?