Exercise 2.5.1
Returns and discounting: optimal policy of a two-action MDP for γ = 0, 0.5, 0.9
Reinforcement Learning › Exercises › Lecture 2 · The RL Problem and Finite MDPs › 2.5 Bellman optimality equations
Consider the continuing MDP shown in Figure 1. The only decision to be made is that in the top state, where two actions are available, left and right. The numbers show the rewards that are received deterministically after each action. There are exactly two deterministic policies, \(\pi_{\text{left}}\) and \(\pi_{\text{right}}\). What policy is optimal if \(\gamma = 0\)? If \(\gamma = 0.9\)? If \(\gamma = 0.5\)?
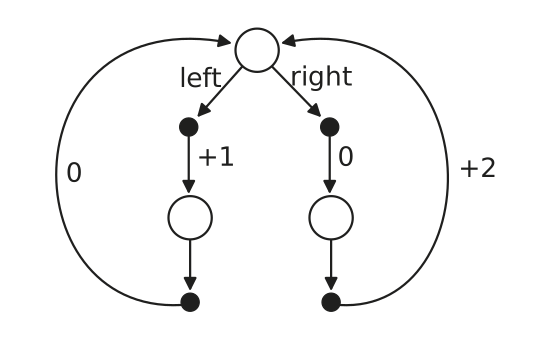
Source: Sutton & Barto (2018), Reinforcement Learning: An Introduction, 2nd ed., Exercise 3.22. The figure of Exercise 3.22 is redrawn from the book. Licensed CC BY-NC-ND 2.0.